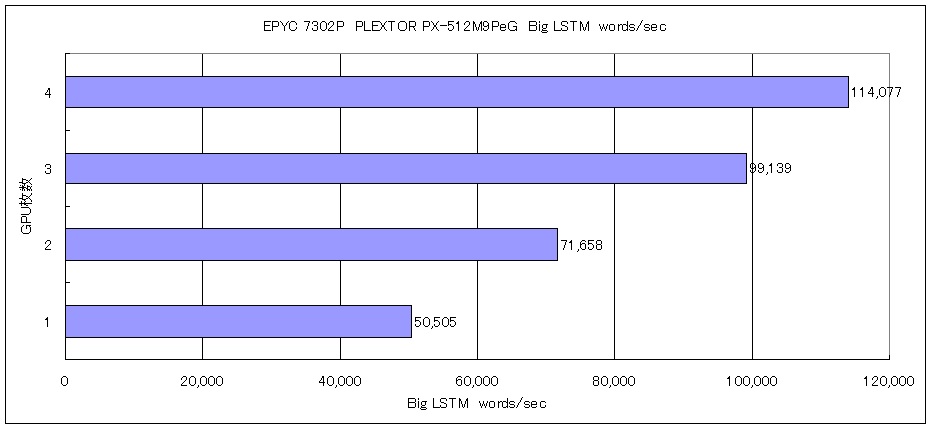
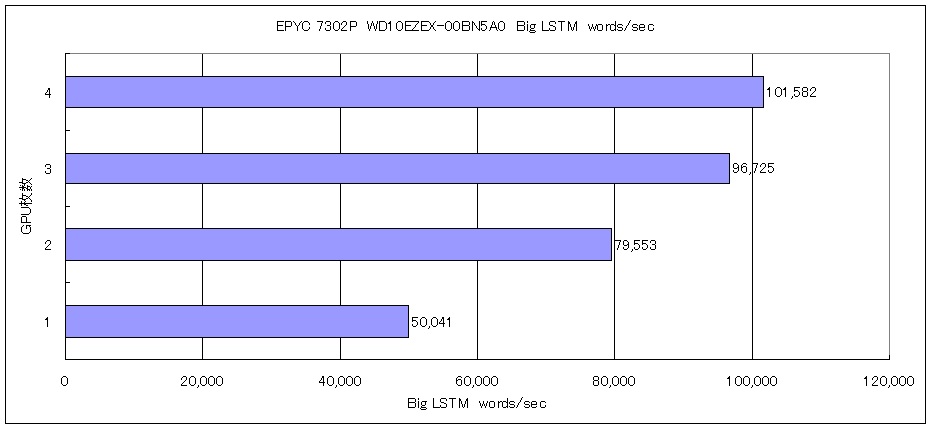
TensorFlow LSTM: Big-LSTM 1 Billion Word Dataset
→数値が大きいほど高性能
AMD Ryzen Threadripper 3990X 64-Core Processor

INTEL Xeon E5 2650 V4 x2

AMD Ryzen Threadripper 3990X 64-Core Processor データ詳細
Big LSTM Red Hat Enterprise Linux release 8.2 RTX2080Ti x2 TITAN RTX x2 CUDA 11.0 AMD 3990x 19.04-py3 – TensorFlow-Training performance (wordssecond) wps=109553 109351 108850 89143 88923 88630


-
最近の投稿
- 第5世代 AMD EPYC 9655 96-Core Processor 192Threads 384GB NVIDIA TITAN RTX PX-512M5Pro 512GBで構成されたArch Linux Kernel7.3.4へ CUDA-toolkit13.5.0をInstall メモリ周波数4800MT/sのマシンに移行して sensors CPU温度12点確認 推移確認 nvidia-smi nvcc -V cat /etc/os-release lsmem lscpuの設定 再現確認は安定している
- Fedora release 43 Kernel6.18.5-200.fc43.x86_64 PHP 8.5.2 Samba4.23.4 Update
- Kernel 7.4-rc3 が公開
- Manjaro Linux Kernel6.18.6-1-MANJARO Update
- Arch Linux Kernel6.18.6-arch1-1 Update
最近のコメント
- 春のたそがれ に 丸山泰男 より
- しだれ桜が咲いていました に 丸山泰男 より
- Intel(R) Core(TM) i7-6700K CPU @ 4.00GHz 4core 8threds 32GB RTX2080Ti PLEXTOR PX-256M9PeGで構成されたUbuntu24.04.3 LTS へ CUDA-toolkit 12.5をInstall してnvidia-smi nvcc -V cat /etc/os-release sensors lsmem nvme list nvme smart-log /dev/nmve0n1 lscpuを設定 に 丸山泰男 より
- Ubuntu 26.04 Daily Build を installしてみた に 丸山泰男 より
- 梅が咲きました に 丸山泰男 より
アーカイブ
- 2026年11月 (43)
- 2026年10月 (64)
- 2026年9月 (73)
- 2026年8月 (57)
- 2026年7月 (55)
- 2026年6月 (46)
- 2026年5月 (57)
- 2026年4月 (67)
- 2026年3月 (60)
- 2026年2月 (65)
- 2026年1月 (54)
- 2025年12月 (58)
- 2025年11月 (68)
- 2025年10月 (65)
- 2025年9月 (71)
- 2025年8月 (81)
- 2025年7月 (81)
- 2025年6月 (83)
- 2025年5月 (66)
- 2025年4月 (56)
- 2025年3月 (67)
- 2025年2月 (67)
- 2025年1月 (66)
- 2024年12月 (71)
- 2024年11月 (66)
- 2024年10月 (73)
- 2024年9月 (79)
- 2024年8月 (93)
- 2024年7月 (86)
- 2024年6月 (58)
- 2024年5月 (83)
- 2024年4月 (89)
- 2024年3月 (90)
- 2024年2月 (86)
- 2024年1月 (89)
- 2023年12月 (77)
- 2023年11月 (74)
- 2023年10月 (82)
- 2023年9月 (70)
- 2023年8月 (73)
- 2023年7月 (59)
- 2023年6月 (63)
- 2023年5月 (57)
- 2023年4月 (51)
- 2023年3月 (65)
- 2023年2月 (58)
- 2023年1月 (63)
- 2022年12月 (74)
- 2022年11月 (78)
- 2022年10月 (69)
- 2022年9月 (70)
- 2022年8月 (64)
- 2022年7月 (38)
- 2022年6月 (62)
- 2022年5月 (58)
- 2022年4月 (54)
- 2022年3月 (65)
- 2022年2月 (54)
- 2022年1月 (65)
- 2021年12月 (87)
- 2021年11月 (90)
- 2021年10月 (93)
- 2021年9月 (90)
- 2021年8月 (89)
- 2021年7月 (88)
- 2021年6月 (85)
- 2021年5月 (81)
- 2021年4月 (68)
- 2021年3月 (69)
- 2021年2月 (59)
- 2021年1月 (62)
- 2020年12月 (63)
- 2020年11月 (61)
- 2020年10月 (66)
- 2020年9月 (63)
- 2020年8月 (72)
- 2020年7月 (92)
- 2020年6月 (89)
- 2020年5月 (92)
- 2020年4月 (91)
- 2020年3月 (94)
- 2020年2月 (85)
- 2020年1月 (77)
- 2019年12月 (91)
- 2019年11月 (3)
- 2019年9月 (2)
- 2019年4月 (1)
- 2019年2月 (1)
- 2018年11月 (1)
- 2018年10月 (1)
- 2018年9月 (1)
- 2018年8月 (1)
- 2018年7月 (1)
- 2018年6月 (1)
- 2018年5月 (2)
- 2018年4月 (3)
- 2018年3月 (1)
- 2018年2月 (1)
- 2018年1月 (1)
- 2017年12月 (1)
- 2017年8月 (1)
- 2017年4月 (1)
- 2017年3月 (1)
- 2017年2月 (1)
- 2017年1月 (1)
- 2016年12月 (1)
- 2016年10月 (2)
- 2016年8月 (3)
- 2016年7月 (7)
- 2016年6月 (3)
- 2016年5月 (5)
- 2016年4月 (3)
- 2016年3月 (2)
- 2016年2月 (3)
- 2016年1月 (4)
- 2015年12月 (3)
- 2015年11月 (4)
- 2015年10月 (10)
- 2015年9月 (7)
- 2015年8月 (8)
- 2015年7月 (23)
- 2015年6月 (2)
メタ情報
固定ページ